yuangang.me
yuangang.me
Home
Publications
Experience
Services
Contact
CV
Large Language Models
arXiv
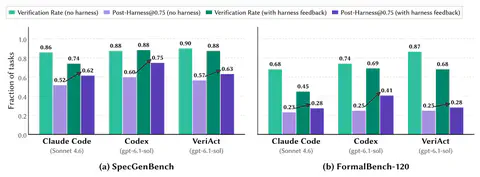
Spec-Harness: Assessing and Guiding LLM-Synthesized Formal Specifications Beyond Verifiability
Md Rakib Hossain Misu
,
Cristina V. Lopes
,
Iris Ma
,
Yuangang Li
,
Shuvendu Lahiri
PDF
Code
DOI
arXiv
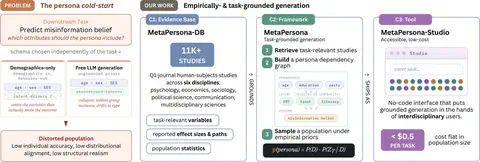
MetaPersona: Task-Grounded Synthetic Populations from Empirical Social Science
Jinyi Ye
,
Yuangang Li
,
Chenxiao Yu
,
Preyashi Poddar
,
Priyanka Dey
,
Longtian Ye
,
Zihan Wang
,
Xiyang Hu
,
Emilio Ferrara
,
Yue Zhao
PDF
DOI
NeurIPS 2026 E&D
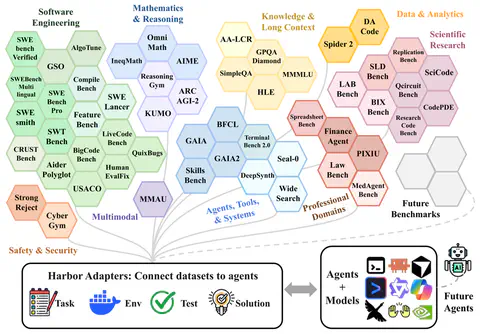
Harbor Adapters and Harbor-Index: Infrastructure and a Curated Meta-Dataset for Large-Scale Agentic Evaluation
Lin Shi
,
Haowei Lin
,
Zixuan Zhu
,
Xiaoyue Zhou
,
Xiang Li
,
Xiangning Lin
,
Yaxuan Deng
,
Han Xu
,
Yuangang Li
,
et al. (120+ authors)
PDF
Code
Dataset
Project
DOI
NeurIPS 2026 E&D
Agents' Last Exam
Yuangang Li
with Team
PDF
arXiv
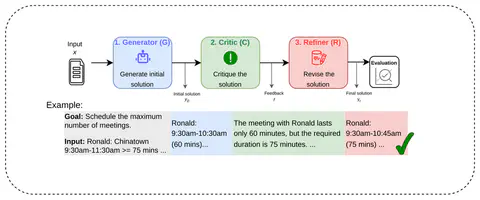
Asymmetric Capacity Allocation in Self-Refinement Pipelines
Zhuoyi Yang
,
Ian G. Harris
,
Salar Hashemitaheri
,
Cassie Huang
,
Yuangang Li
,
Hyunwoo Oh
,
Paul Dourish
,
Tony Givargis
,
Mohsen Imani
,
Li Zhang
PDF
ACL 2026 Findings
LLM-Guided Semantic Bootstrapping for Interpretable Text Classification with Tsetlin Machines
Jiechao Gao
,
Rohan Kumar Yadav
,
Yuangang Li
,
Yuandong Pan
,
Jie Wang
,
Ying Liu
,
Michael D. Lepech
PDF
EMNLP 2026
Beyond Output Correctness: Benchmarking and Evaluating Large Language Model Reasoning in Coding Tasks
Yuangang Li
,
Justin Tian Jin Chen
,
Ethan Yu
,
David Hong
,
Iftekhar Ahmed
PDF
DOI
AAAI 2026
Mitigating Hallucinations in Large Language Models via Causal Reasoning
Yuangang Li
,
Yiqing Shen
,
Yi Nian
,
Jiechao Gao
,
Ziyi Wang
,
Chenxiao Yu
,
Li Li
,
Jie Wang
,
Xiyang Hu
,
Yue Zhao
PDF
Code
DOI
ACL 2025 Findings
AD-LLM: Benchmarking Large Language Models for Anomaly Detection
Tiankai Yang
,
Yi Nian
,
Li Li
,
Ruiyao Xu
,
Yuangang Li
,
Jiaqi Li
,
Zhuo Xiao
,
Xiyang Hu
,
Ryan A. Rossi
,
Kaize Ding
,
Xia Hu
,
Yue Zhao
PDF
DOI
arXiv
A Large-Scale Simulation on Large Language Models for Decision-Making in Political Science
Chenxiao Yu
,
Jinyi Ye
,
Yuangang Li
,
Zheng Li
,
Emilio Ferrara
,
Xiyang Hu
,
Yue Zhao
PDF
»
Cite
×